Frontier compute.
In ~3 months.
Dedicated NVIDIA Blackwell GPU clusters for training and inference.
Choose how
you deploy.
Your own GPU cluster.
Dedicated NVIDIA compute. Your GPU, cluster size and orchestration.
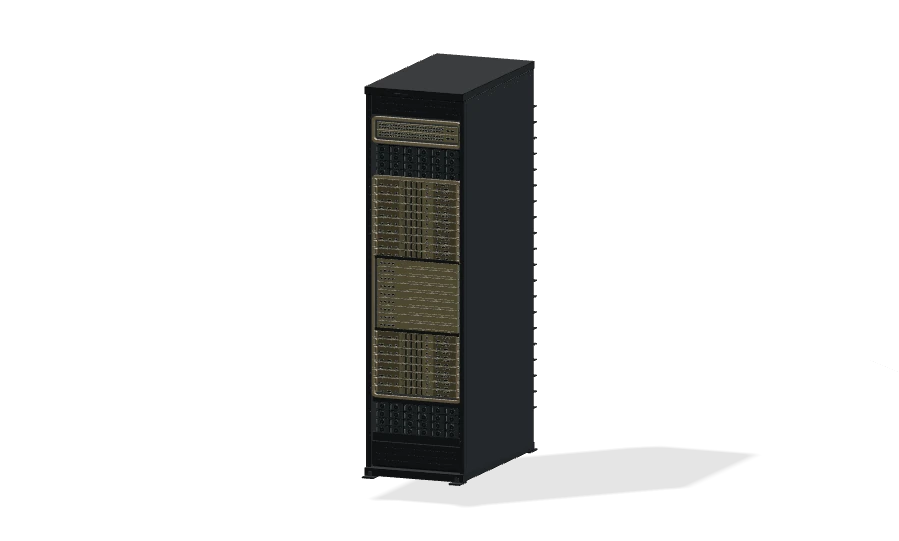
NVIDIA Blackwell.
From a server GPU to a complete NVLink rack.
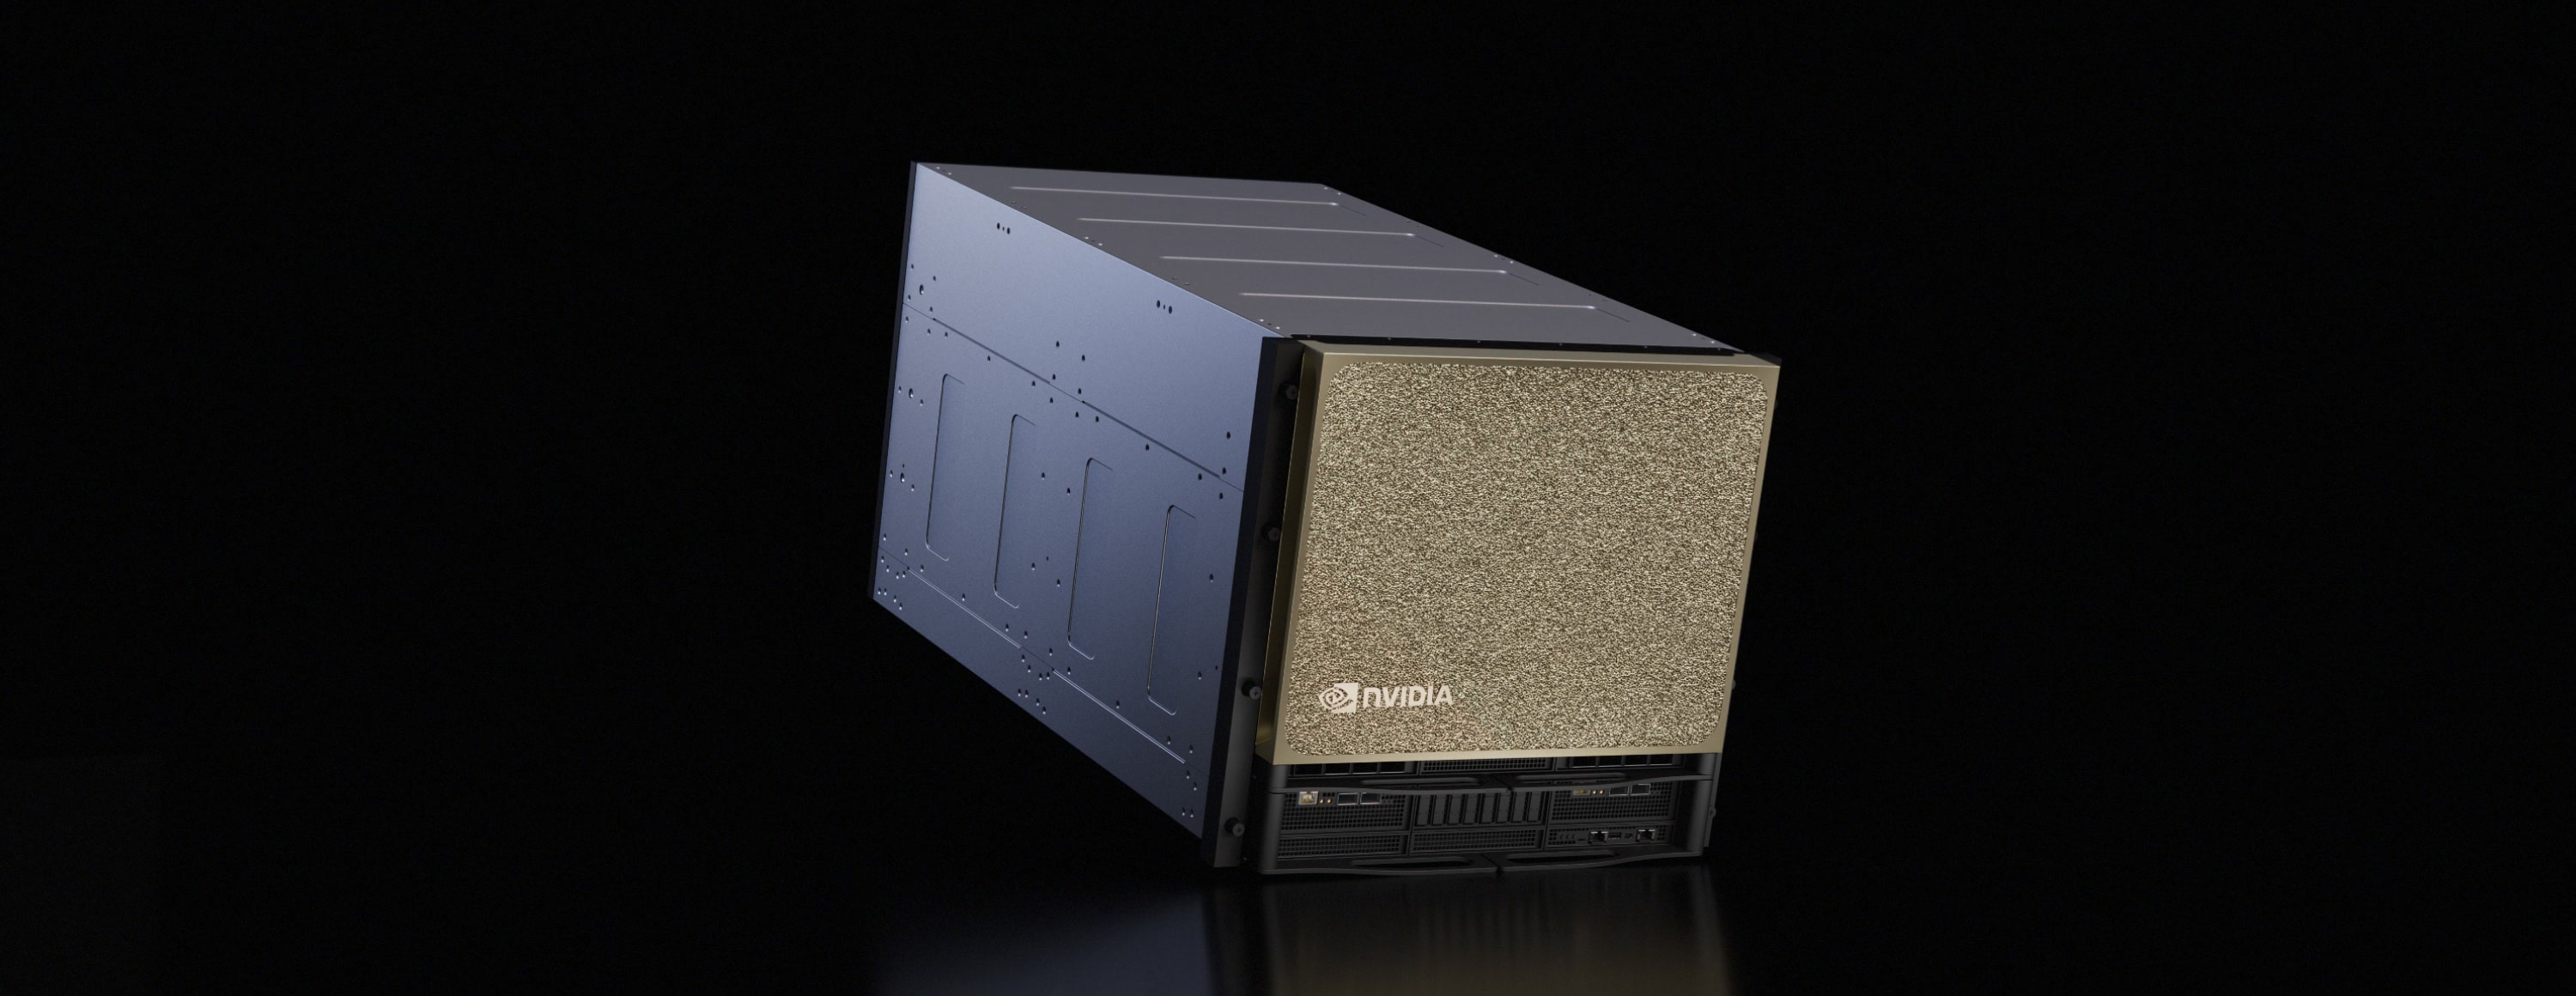
NVIDIA B300
Blackwell Ultra for demanding training runs and reasoning workloads.
- Architecture
- Blackwell Ultra
- GPU memory
- HBM3e
- Platform
- 8-GPU NVLink system
From agreement
to deployment.
A target of about three months.
Timing depends on configuration and site readiness. Confirm the schedule in your agreement.
Agree the scope
Confirm your capacity, hardware and site requirements. Set the delivery schedule in your agreement.
Engineer the deployment
Plan power, cooling and connectivity around the hardware and its operating requirements.
Build and integrate
Prepare the facility and bring the electrical, cooling and network systems together.
Validate and hand over
Commission the infrastructure, complete acceptance checks and hand over the deployment.
Power is part
of the product.
Energy supply and cooling.
Planned alongside your compute.
- Renewable supply
- Long-term power agreements support renewable supply. The mix varies by site and over time.
- Closed-loop cooling
- Facility cooling is designed without evaporative water consumption.
- Site efficiency
- PUE depends on load and operating conditions. Review the figures for your deployment.
Our planned
U.S. footprint.
- Reserved power
- 1,346 MW
- Planned sites
- 18
Utah
Washington, Wasatch Front & Vernal
946MW reserved
across 7 sites